AI applications become easier to assess when they are tied to an operational question. Can traffic features help prioritize an investigation? Can text classification organize a queue? Which result would change what an engineer does next?
The original article surveyed AI across industries. This revised guide focuses on the part connected to my portfolio: Python applications, network traffic experiments and natural language processing. The examples are evaluation ideas and lab references, not claims of deployed AI services in every industry.
Separate automation, prediction and generation
A Python script that reads inventory and sends a known command is automation. A classifier that learns from labeled examples estimates a category. A generative system produces new text or another output. They can work together, but they need different acceptance checks.
For a deterministic task, inspect the input, rules and resulting state. For an ML model, evaluate its errors on appropriate held-out data. For generated text, check that statements are supported and that an engineer remains responsible for consequential decisions.
Choose a bounded use case for AI-assisted operations
Possible infrastructure experiments include traffic classification, grouping recurring incident descriptions and summarizing a sanitized maintenance record. Before implementation, define the output, the person who uses it and what a wrong answer would cost.
For example, a label saying suspicious traffic should provide enough underlying evidence for review. A label without the observation time, feature context or affected flow can add noise to a security queue.
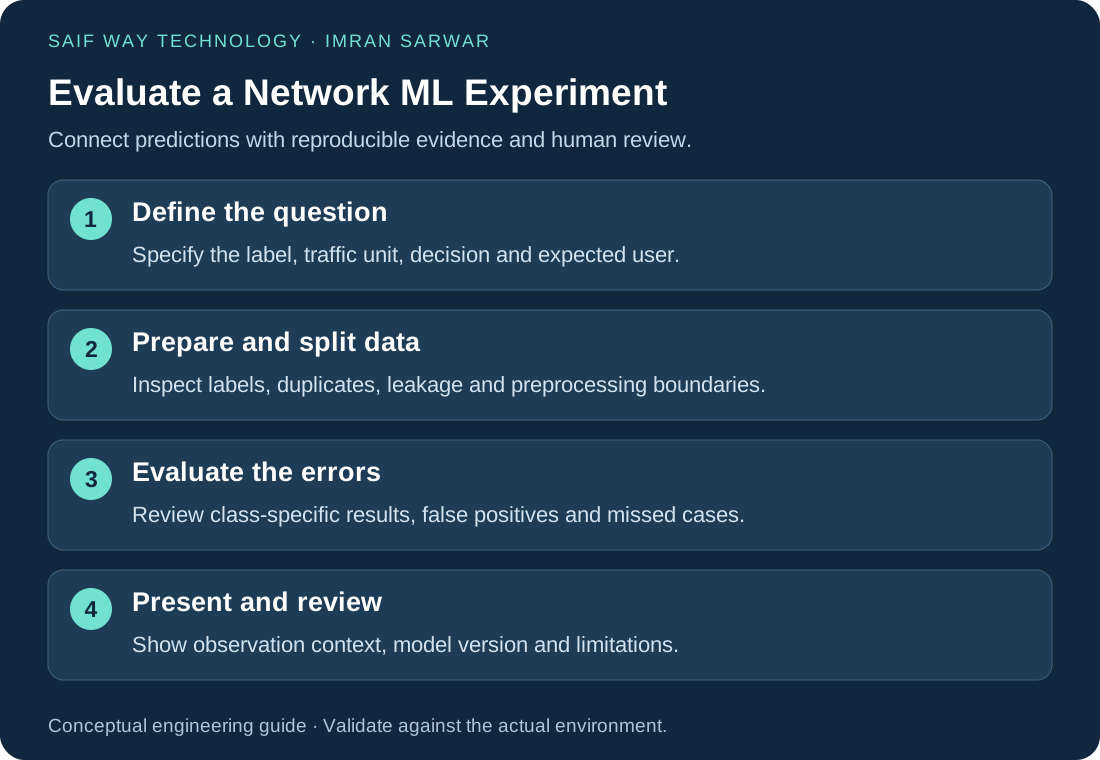
Use the right data and a simple baseline
A collection of examples may be incomplete or biased toward the lab in which it was created. Record where it came from, what its labels mean and what is excluded. Keep unrelated sessions or duplicate records from making the evaluation appear stronger than it is.
Compare the model with a useful baseline: a rule, a simple classifier or the current manual method. More complexity is justified only when it improves the defined outcome. Scikit-learn’s guidance on data leakage explains why information from evaluation data must not leak into training.
Portfolio evidence: what the two AI examples demonstrate
My network threat-detection project connects traffic features with a Python/Flask interface. It is a simulated-network project, so deployment to an operational network would require separate validation and monitoring.
The text emotion-recognition project explores NLP classification. A text label is a model output, not direct knowledge of a person’s internal state. A different vocabulary, domain or label definition can change its usefulness.
Define human review and operational handover for AI outputs
Document uncertain outcomes, unsuitable inputs and the action that requires human approval. Keep sensitive data out of unapproved services. Record the model and data version used so an unexpected result can be reproduced.
For an internal dashboard or a Python integration, explain the workflow first. A technical scope review can establish whether a conventional script, a small application or an ML experiment is the right fit. The goal is a useful and explainable result, not adding AI to a task that already has a reliable simpler solution.