Machine learning for network intrusion detection uses traffic-derived features to classify behavior or flag unusual patterns. Its usefulness depends on the data, the evaluation and the action an analyst can take from the result.
My simulated-network cyber attack detection project connects Python traffic processing with a Flask interface. This article explains the experiment design. It does not claim that a model validated in one simulation is ready to detect threats in an unrelated production network.
Define the network-threat detection question
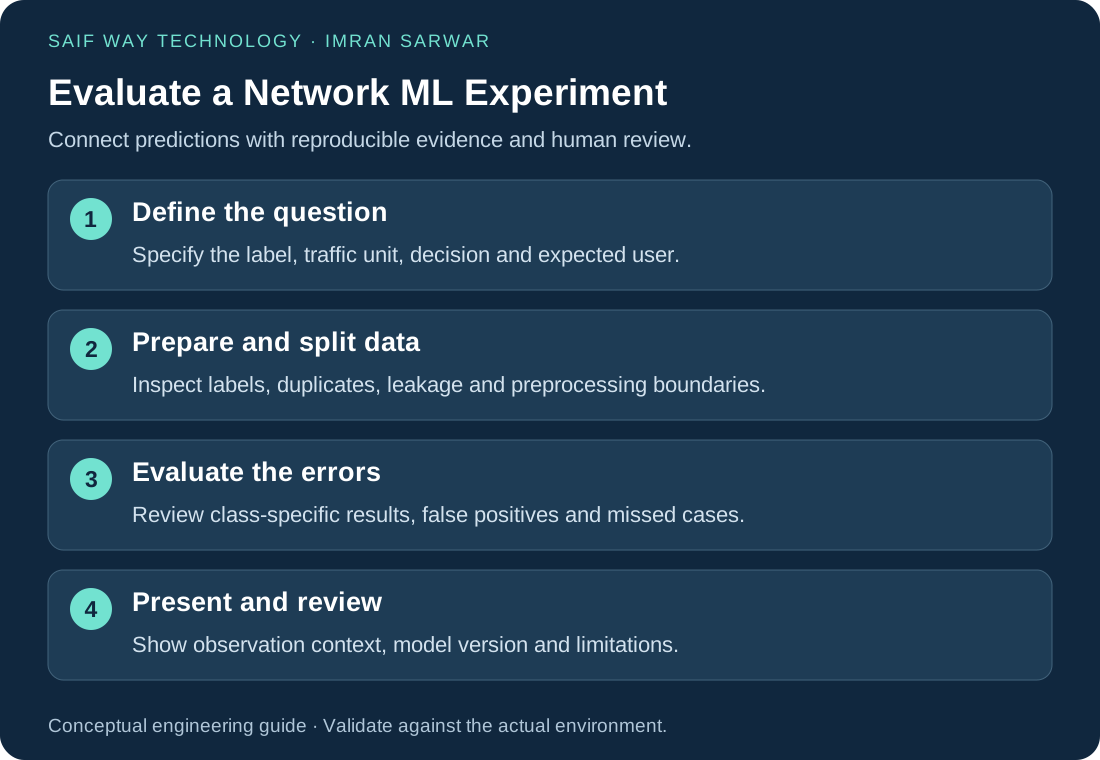
Specify what the model is expected to distinguish and the unit being classified: a packet, flow, session or time window. A broad label such as attack is difficult to interpret unless its definition and collection method are clear.
Record the traffic source, label process, class balance and scenarios excluded from the experiment. If training data does not contain a behavior, a reported score cannot establish reliable detection of it.
Inspect traffic features and leakage
Candidate features include duration, packet or byte counts, protocol and connection frequency. Their meaning depends on how traffic is collected and aggregated. Missing values, duplicate records and inconsistent preprocessing can change the result.
Split the evaluation data before fitting preprocessing steps. Also check whether nearly identical traffic, the same capture session or a label-revealing identifier appears on both sides of the split. The correct split depends on what future traffic the experiment is intended to represent. See scikit-learn’s leakage guidance for the underlying evaluation problem.
Report errors an analyst can understand
Accuracy can hide failures when normal traffic dominates. Review the confusion matrix and class-specific precision and recall. A false positive adds investigation work; a false negative is missed activity. Choose metrics around that operational trade-off.
Do not label an arbitrary model score confidence in the ordinary sense without checking its interpretation. Keep the dataset, split method, model version and threshold with the result. The scikit-learn evaluation reference explains the metrics used for classification.
Make the dashboard explain the observation
A useful view connects the classification to the observed time, traffic unit, relevant features and model version. Give the reviewer a way to distinguish a suspicious prediction from a confirmed incident.
For a production proposal, consider input drift, unavailable features, model failure and a human escalation path. Adding a dashboard does not remove the need to validate the detection process.
Review the threat-detection lab evidence and remaining scope
The project case study and repository provide the implementation context. The observability article explains why correlated evidence is more useful than isolated alerts.
For a Python dashboard or data-processing workflow, use the engineering inquiry form. Include the dataset or signal source, required output and validation goal. Production detection capability requires separate evidence and scope agreement.