A Nornir job reaches most devices, but the next task skips a few hosts. That can be deliberate failed-host handling rather than an inventory mistake. Before resetting state, preserve the original results and decide which failures are safe to retry.
Lab status: This is a proposed exercise, not a completed device test or client case study. Code examples require validation against your image and dependency versions. My documented background is NOC/data center operations, multi-vendor Netmiko workflows and Python/Flask integration.
Offline example checks: October 20, 2026: synthetic retry selection and recovery assertions passed with Nornir 3.5.0. No device connection was opened.
How does Nornir track failed hosts between tasks?
Nornir maintains shared state identifying hosts whose tasks failed. Later task execution can exclude those hosts unless explicitly told to include them. The on_failed and on_good run controls let a workflow select failure and success groups. Check the API for the version installed in your environment.
A failed task changes shared failed-host state, so subsequent tasks may exclude that host. Preserve the initial result before retrying; otherwise an operator cannot distinguish a recovered transport fault from a silently skipped target.
Why can resetting every failed host hide the original failure?
A global reset makes previously failed devices eligible without establishing recovery. Use recover_host(host) only after a validated successful retry, and retain an audit trail. A no-op synthetic retry demonstrates orchestration, not restored device reachability.
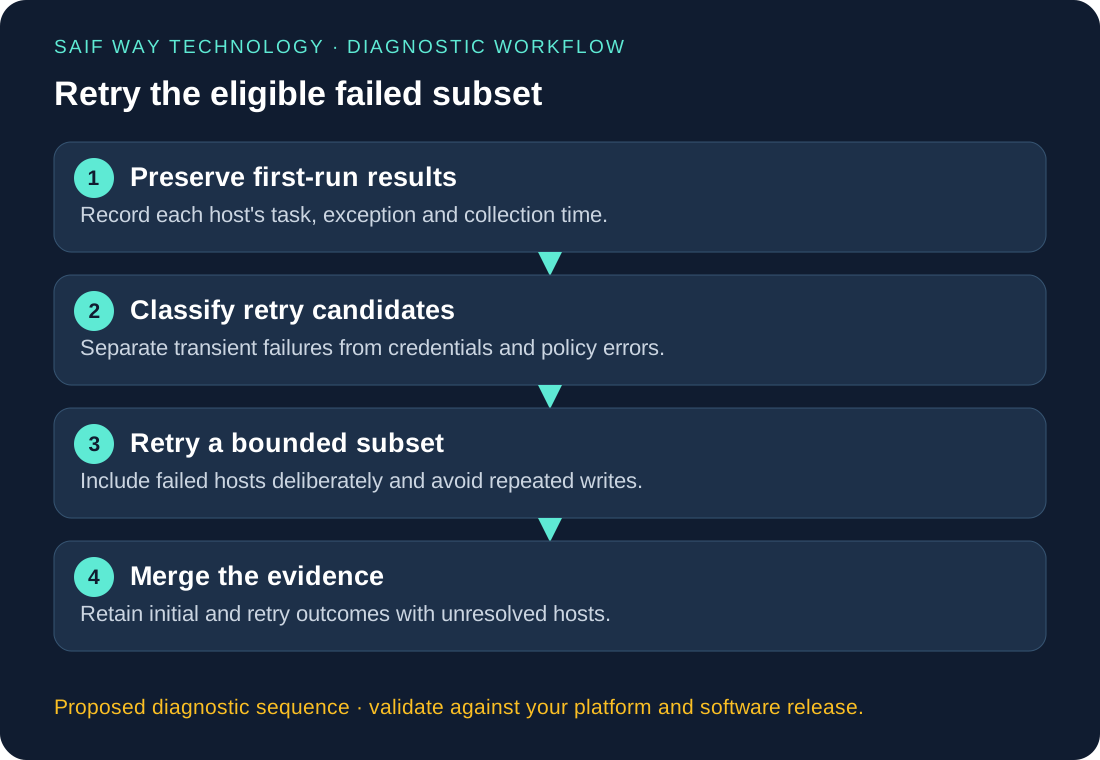
Proposed GNS3/EVE-NG lab: isolate retry candidates
For the offline task, supply these local files; no SSH credentials are needed because the task does not open a connection.
# config.yaml
inventory:
  plugin: SimpleInventory
  options:
    host_file: hosts.yaml
    group_file: groups.yaml
    defaults_file: defaults.yaml
runner:
  plugin: serial
# hosts.yaml
r1: {}
r2: {}
Save {} in both groups.yaml and defaults.yaml. Run from that directory in a recorded Nornir 3.x environment. Only after offline selection is correct should a separately reviewed task use Netmiko to collect a read-only command on an approved lab device.
Python: select failed hosts with on_failed and on_good
After the existing retry, inspect each MultiResult.failed before recovery. The additional assertions below prove only that the synthetic good host was not rerun and that the successful retry can be removed from failed-host state. Use an error-category allowlist before admitting live transport failures to this retry path.
from nornir import InitNornir
from nornir.core.task import Result

nr = InitNornir(config_file="config.yaml")

def sample_check(task, fail_r2=False):
    failed = fail_r2 and task.host.name == "r2"
    return Result(host=task.host, failed=failed, result="synthetic check")

first = nr.run(task=sample_check, fail_r2=True)
initial_failed = sorted(nr.data.failed_hosts)
retry = nr.run(task=sample_check, on_failed=True, on_good=False)
print({"initial_failed": initial_failed, "retried": sorted(retry.keys())})
Assert retry selection before clearing failed-host state
# Continue the synthetic example above; no network operation is performed.
assert initial_failed == ['r2']
assert set(retry.keys()) == {'r2'}
for host, multi_result in retry.items():
    if not multi_result.failed:
        nr.data.recover_host(host)
assert 'r1' not in retry
assert not nr.data.failed_hosts
Which failures are safe to retry in an operational job?
Keep authentication denial, unsupported command and schema failure out of automatic retry unless an operator has approved a correction. Bound attempts and total job duration, and cap concurrency per site/AAA service. Replaying a write needs a separate idempotency/readback design.
What should a failed-host retry report preserve?
Record the original failure, eligibility decision, attempts, final validated collection and last success timestamp. Skipped hosts remain part of coverage. A Flask report should display unresolved hosts instead of returning only the successful result dictionary.
Related troubleshooting and implementation
Explore the network automation troubleshooting collection to connect this issue to adjacent workflows. The Netmiko, NETCONF and RESTCONF comparison helps when you are choosing an interface rather than fixing an existing implementation.