A connectivity complaint can originate in a network path, an endpoint, name resolution, identity or the application itself. A useful NOC workflow tests those possibilities in a controlled sequence instead of turning the first assumption into a configuration change.
This article expands an operational lesson from my infrastructure support experience: the issue appeared to be network-related, but comparison checks pointed toward the machine. The original note does not identify a confirmed driver, hardware or application defect, so those remain possible investigation directions rather than a claimed final diagnosis.
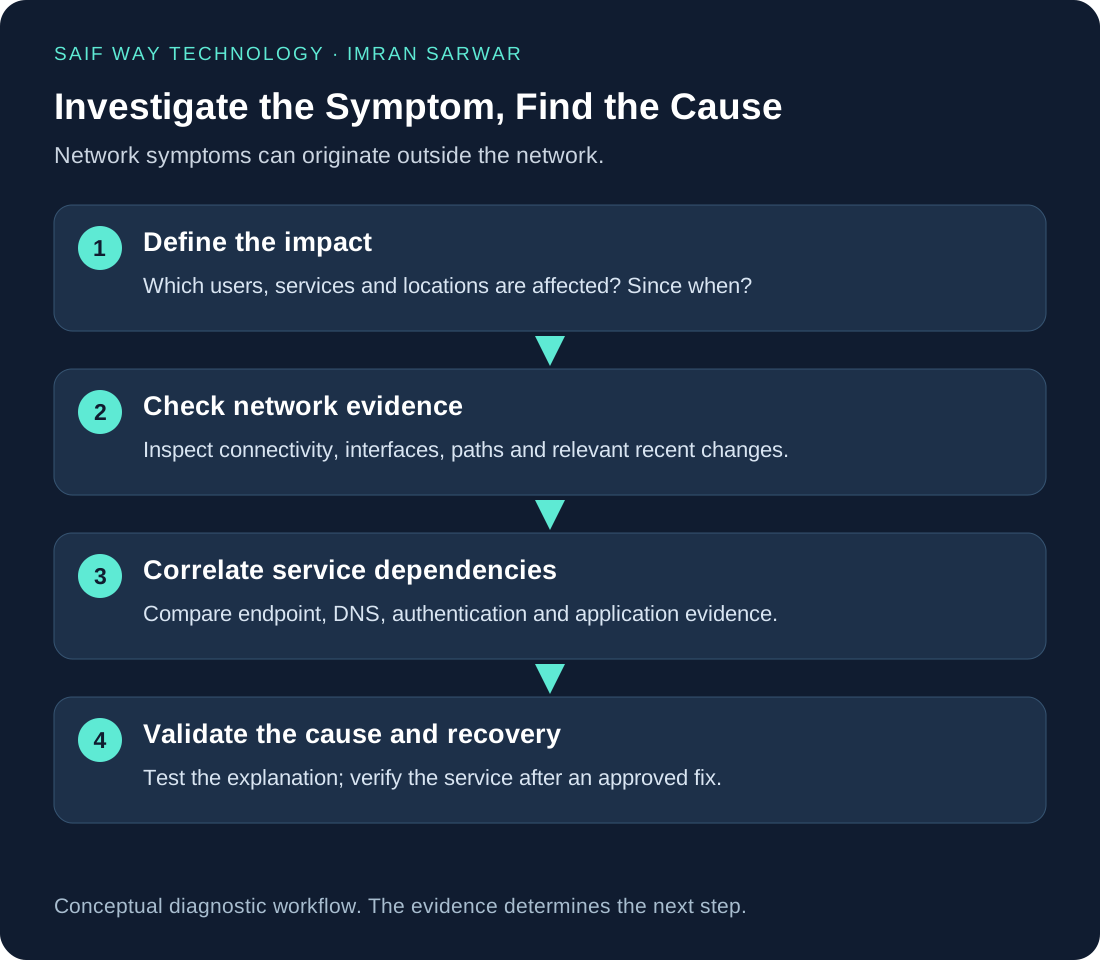
Define what is failing and for whom
Record the affected user, device, location, application, start time and exact operation. Ask whether the problem is constant or intermittent and whether other users are affected. Capture the message or behavior before changing anything.
A statement such as the network is slow needs refinement. Is name resolution delayed, a connection failing, a login denied or a transaction taking longer? Different symptoms require different observations.
Check the path with a defined test
Inspect local link and interface state, addressing, gateway and the route relevant to the destination. Compare the result with the expected path. A cable or access-port problem may be visible locally; a return-path issue may need evidence from another point.
A ping can help establish a particular form of reachability if permitted, but it does not validate DNS, authentication or an application transaction. Record exactly what the test demonstrates and what it leaves untested.
Compare affected and working paths during NOC troubleshooting
Compare a known-working client with the affected one. Keep the destination, operation and time window as similar as possible. If the problem follows a machine across locations, that is evidence for endpoint investigation; it does not automatically prove that the network has no role.
Consider differences in identity, policy, software, name resolution and service dependencies. Change one variable at a time when possible, so the result has a useful interpretation.
Example record for comparing working and failing paths
Use comparisons to narrow the next investigation step rather than declare a root cause early. The cases below are illustrative and do not add an unrecorded diagnosis to the original incident.
| Comparison | Useful observation | Remaining uncertainty |
|---|---|---|
| Same service from a second client | Whether the symptom is shared | Identity, policy and application differences |
| Same device on another approved path | Whether the problem follows the machine | Local configuration and destination-specific behavior |
| Name lookup versus direct reachability | Whether resolution and transport differ | Whether the real application uses the same path and endpoint |
| Before and after an approved correction | Whether the original operation recovers | Recurrence and untested dependencies |
Keep the exact target, time and operation with each result. Two screenshots of different tests are difficult to compare if those conditions are missing.
A concrete lab example: routed LAN and wireless connectivity
My multi-router LAN and port-security repository provides a separate, inspectable learning example. Its README documents two LANs, RIP v2 route exchange, wireless clients, WPA2 and switch port security. The repository includes a Packet Tracer topology, a report and connectivity screenshots. This is simulation evidence, not evidence from the operational incident described above.
The documented validation includes inter-LAN ping, router connectivity, route propagation, wireless connectivity and port-security violation tests. The engineering value is in separating those questions: a router route does not prove a wireless client associated successfully, and a working authorized client does not prove an unauthorized client was blocked.
For a similar connectivity complaint, I would use the following read-only Cisco IOS checks on the relevant devices. These are suggested diagnostic commands, not a captured transcript from the repository. Replace the interface with the actual affected access port and confirm command support on the device version.
show interfaces status
show vlan brief
show interfaces FastEthernet0/1
show port-security interface FastEthernet0/1
show port-security address
show ip route
Use interface status and errors to investigate the local link, VLAN information to check access placement, port-security state to investigate MAC limits and violations, and the router’s routing table to check the destination path. A historical violation counter needs a time correlation; it does not by itself establish the cause of today’s complaint. Do not disable port security or clear counters just to make the symptom disappear before recording the evidence.
Extend connectivity checks to DNS and identity services
My campus network lab documentation describes VLANs, OSPF, DHCP, DNS, Active Directory and Fortinet policies. Those dependencies explain why remote network troubleshooting often crosses into systems support. If an address is reachable but a domain resource fails by name, the next test should include the configured DNS server and the exact lookup, rather than an immediate routing change.
For example, these Windows commands are an illustrative collection sequence. server.example.com is a placeholder, and no successful output is implied:
ipconfig /all
Resolve-DnsName server.example.com
Test-NetConnection server.example.com -Port 443
Check whether TCP 443 is actually the service under investigation; another application may use a different port. Keep lookup, transport, login and application results separate. The campus README establishes the lab’s documented components, not a measured production availability improvement or a confirmed DNS failure in the original NOC incident.
Hand off an evidence-based hypothesis
If the next investigation belongs to an endpoint or application team, provide the affected scope, successful and failed tests, times and remaining uncertainty. Avoid an escalation that only says network is fine.
An endpoint investigation may examine adapter behavior, local configuration, operating-system events or the application. Those are hypotheses until confirmed. The observability article explains how related signals can support the next test without proving causation by themselves.
Verify recovery using the original operation
After an approved correction, repeat the user-visible action and relevant comparison checks. Record the result and whether recurrence still needs monitoring. A cleared alarm is not always the same as a recovered service.
The campus network lab and port-security lab provide related connectivity examples. My professional profile describes the infrastructure background behind this approach.
For a remote support inquiry, include the environment, business impact, time zone and checks already attempted. Discuss the troubleshooting scope before sharing access or arranging production work.