A resilient network security architecture must remain understandable when a link, device, identity service or control fails. The useful question is what happens to the required business service, not simply whether a second appliance exists.
This guide builds on my hybrid backup and campus labs and my infrastructure operations perspective. It focuses on failure and recovery testing. The separate security-by-design checklist covers the decisions to make before a deployment.
Identify security and infrastructure failure domains
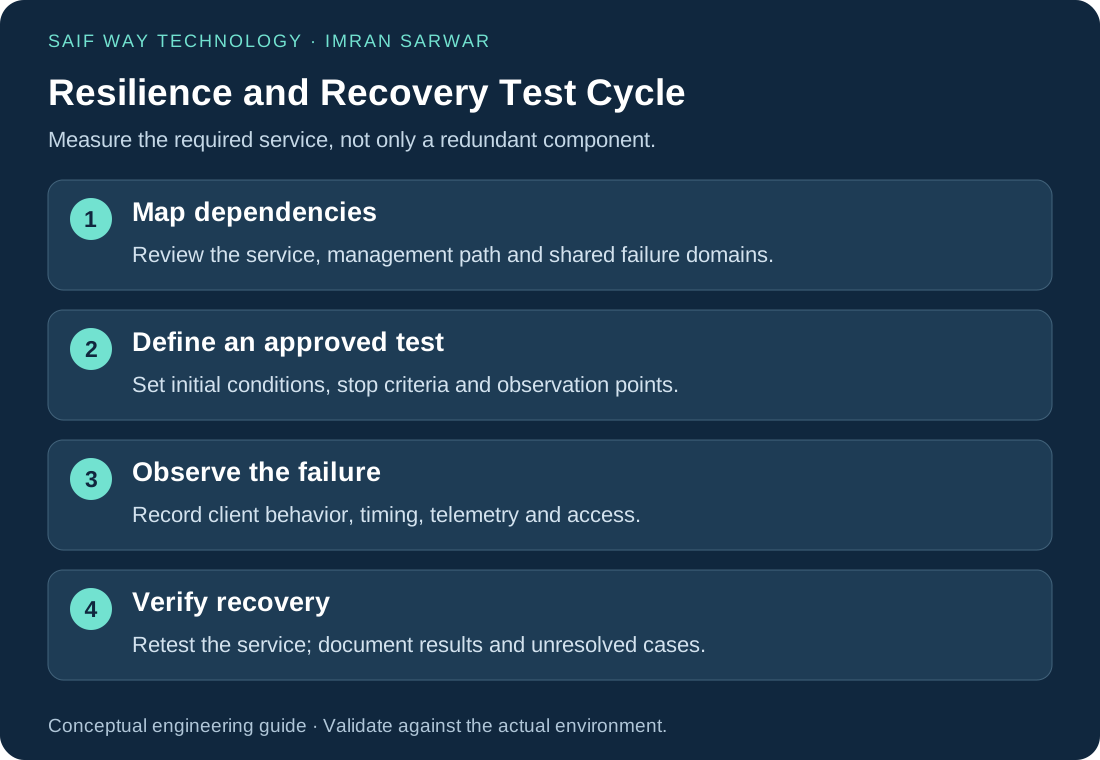
Map what each redundant component depends on: power, physical path, upstream connectivity, credentials, DNS, time and management access. Two devices can still fail together if they share a critical dependency.
Select the service you intend to preserve and describe its acceptable degradation. A route converging after a link failure is a network observation; it does not establish that a storage transaction or application session recovered correctly.
Review security and availability together
A denied access request can be correct enforcement or an unexpected outage. Decide which operations should continue during identity, logging or management failures and which require a controlled stop. Document the decision with the system owner.
Protect recovery access as carefully as everyday administration. A recovery path that depends on the same unavailable service may not help during the incident. Check how the responsible operator can reach the system without widening routine access unnecessarily.
Define a repeatable resilience test
For each approved scenario, record the initial state, injected failure, observation points and recovery procedure. Include the person who can stop the test. Start in a lab or staging environment; a production exercise needs its own authorization and impact assessment.
Observe client behavior, return paths, monitoring and administrative access. Retain timestamps and failed checks. If a test passes, state its scope and conditions instead of turning one result into a general uptime guarantee.
Verify the restore, not only the backup
A backup is valuable when it can support an agreed restore. Check the recovery inputs, access, configuration version and application outcome. The hybrid backup network walkthrough separates transport checks from service-level recovery.
For design context, the UK NCSC’s secure design principles provide a reference framework. The test plan and project evidence here are practical engineering examples, not an assertion of formal assurance against that framework.
Example failure-test record
For each exercise, name the service, approved disruption, expected behavior, observation points and recovery owner. These illustrative cases help define the test; they are not a claim that every scenario was exercised in my labs.
| Scenario | Question to answer | Evidence to retain |
|---|---|---|
| Primary network path becomes unavailable | Does the required service recover through the alternative? | Route events, client behavior and recovery timestamps |
| An identity dependency cannot be reached | Which actions continue, fail or require escalation? | Access results and relevant service events |
| A configuration must be restored | Can the team recover the intended state? | Configuration version, restore steps and service checks |
State the acceptance condition before the exercise. A route converging after a link failure is a network observation; it does not establish that a storage transaction or application session recovered.
Document resilience findings, owners and recovery actions
Document the expected failure behavior, where evidence appears and what remains outside the test. Identify who owns follow-up actions. A clear unresolved dependency is more useful than a diagram labeled highly available with no supporting exercise.
The hybrid network project and campus lab show my design context. For help investigating an existing infrastructure problem, use remote network support and include the service impact and evidence you already have.